A unified approach for security & control
Enterprises now run several models across several clouds, with agents that touch business data and systems. Teams want the right model for each job. Security and IT need consistent control over access, data, and cost.
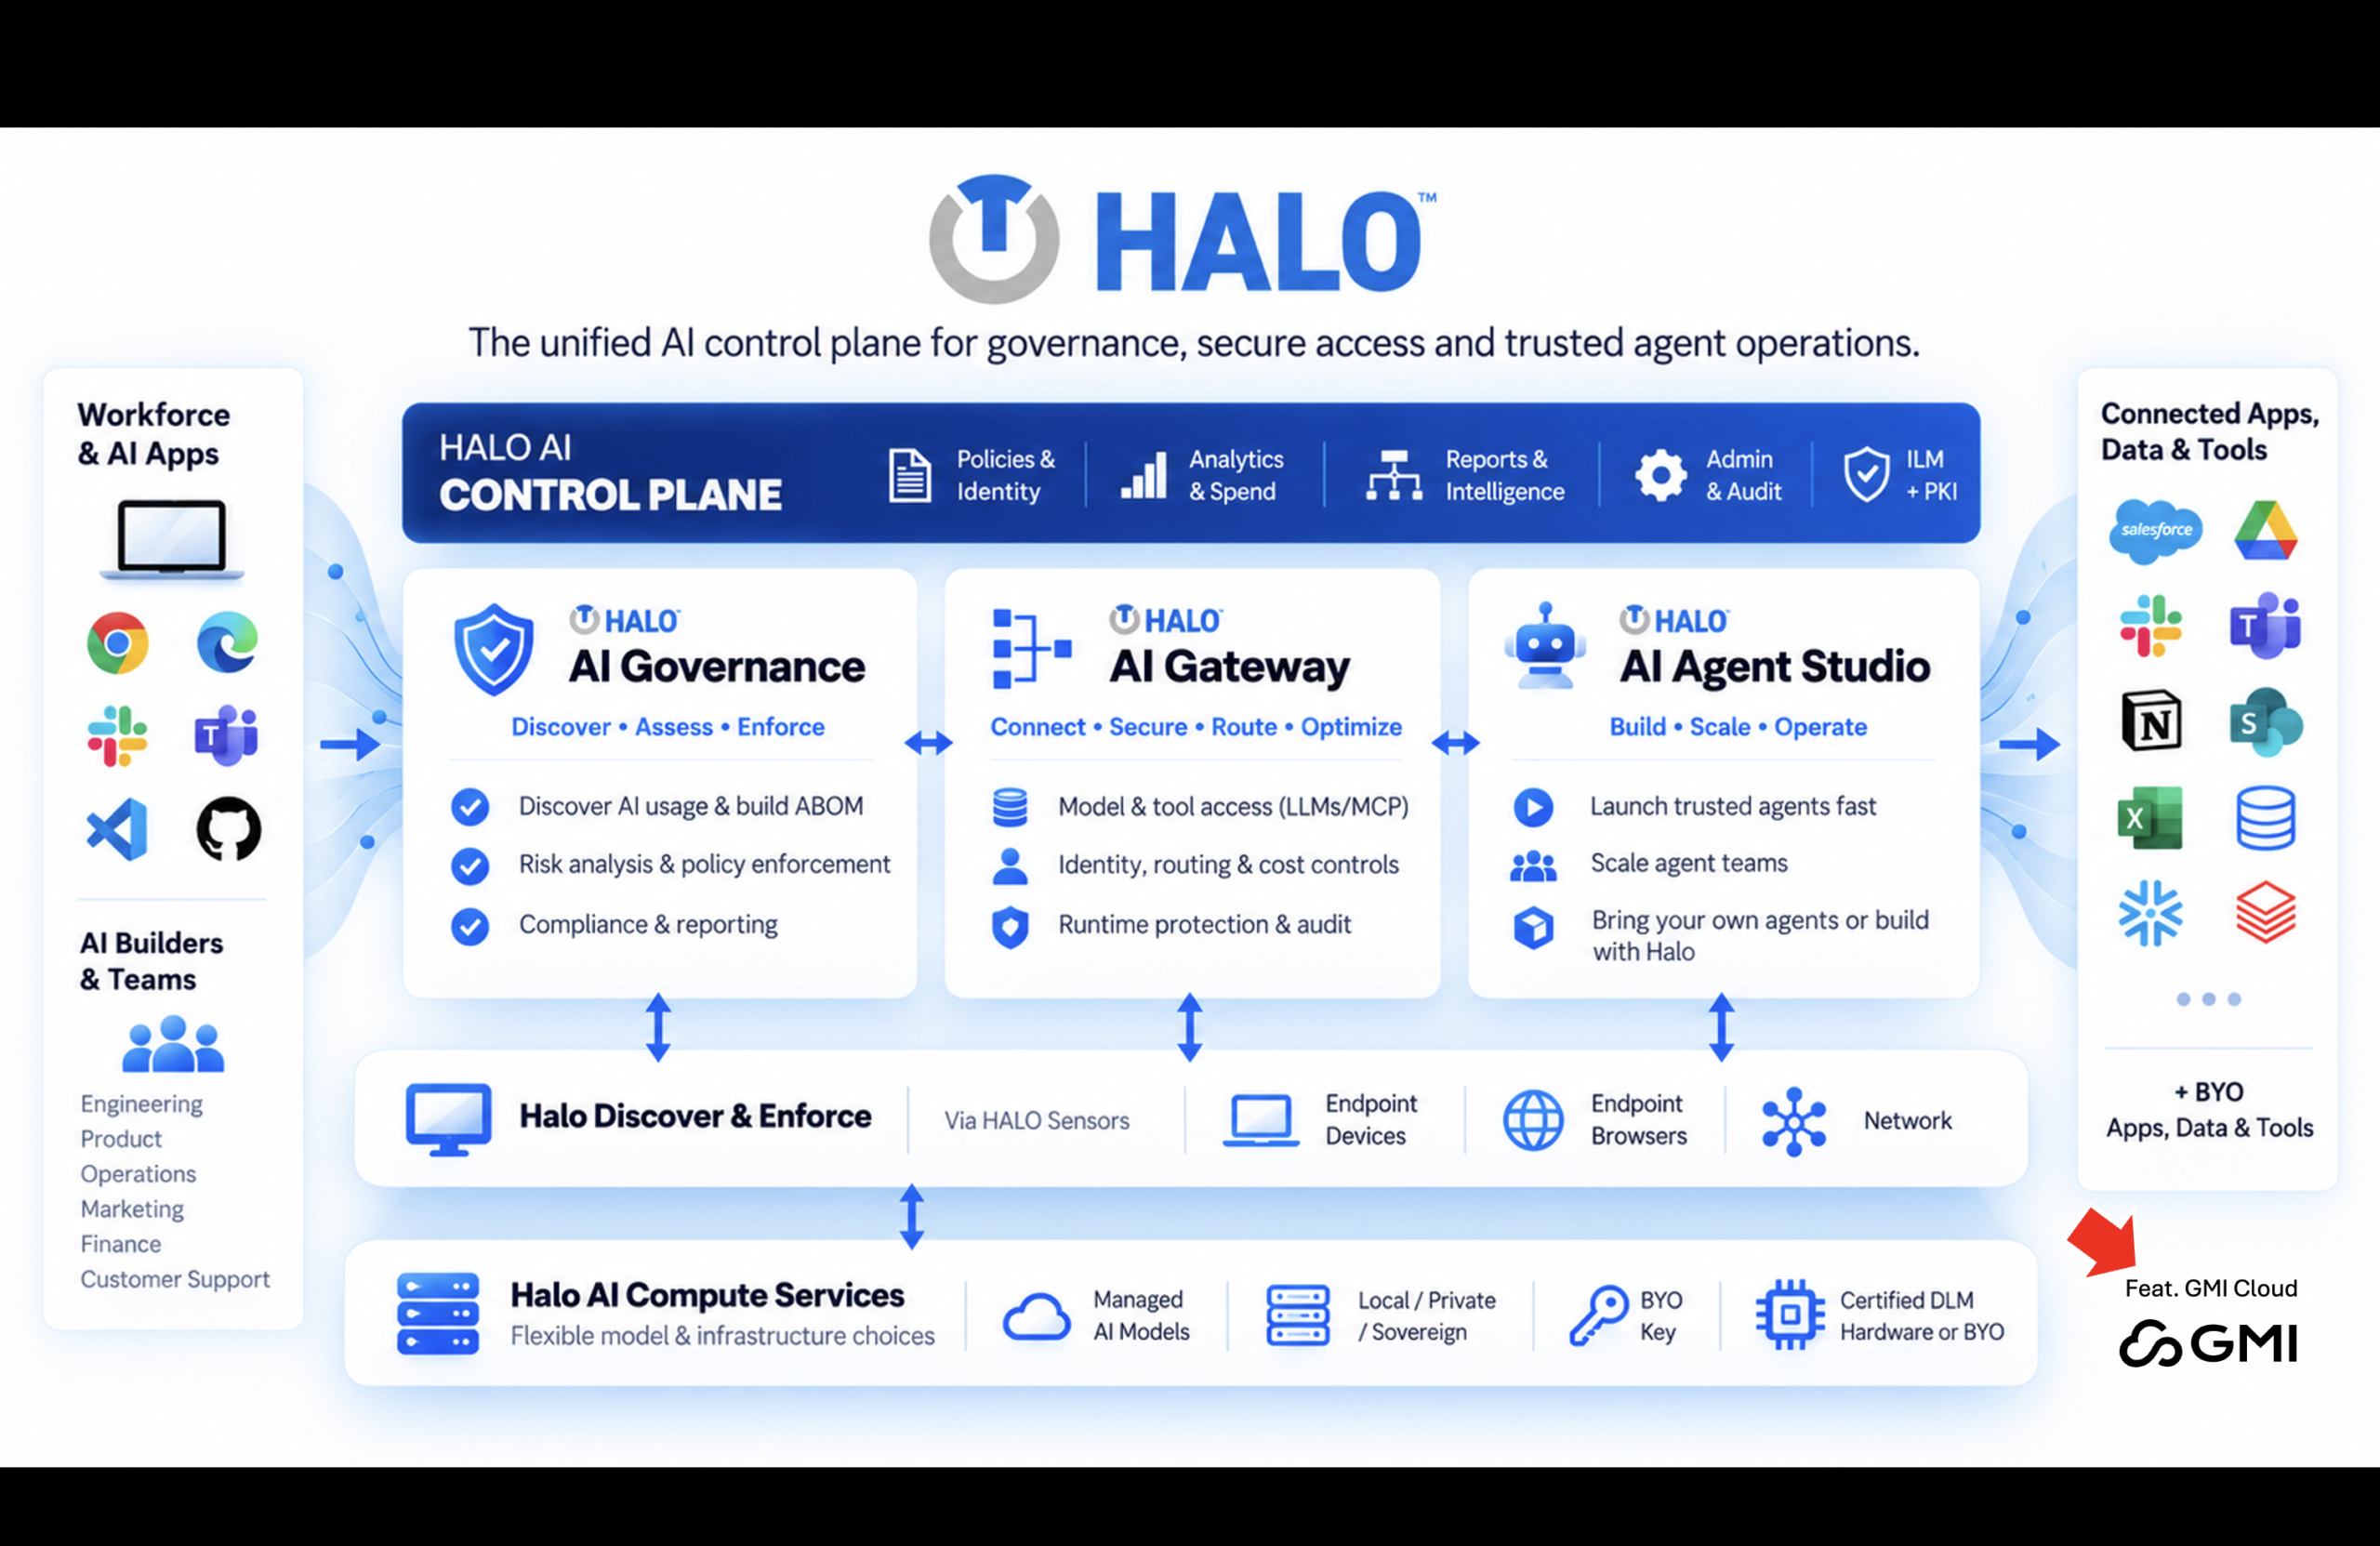
OmniTrust and GMI Cloud are connecting OmniTrust Halo, a security and governance control plane for enterprise AI, with GMI Cloud’s inference platform, including MaaS with access to 300+ models and Prime Inference, along with Model Router for workload-aware model selection and AgentBox for isolated agent execution. Through OT Halo’s External AI Gateway, organizations get a unified front door for desktop assistants, developer tools, and autonomous agents. OT Halo sets the boundaries to keep AI simple, secure, and efficient. GMI Cloud picks the model and runs the work inside them.
One agent, start to finish
Take a customer support agent that handles refunds. It reads each ticket, checks order history, decides whether a refund is warranted, and issues it in the billing system. Before it touches a ticket, OT Halo settles the governance question.
Through OmniTrust’s comprehensive AI governance approach, security teams find the AI already in use, decide what to sanction, and set policy: who can deploy this agent, which models and tools it can use, which credentials it gets, what it can spend, which actions need human approval, and what evidence is kept.
Whether requests originate from desktop clients, developer environments, or automated services, traffic enters through the OT Halo External AI Gateway. The external gateway verifies user identity and enrolled devices, keeps provider credentials protected in the cloud, and checks hard budget caps before dispatching calls to GMI Model Router and GMI inference. Approved agent actions then run safely in GMI AgentBox.

The right model for each step
Summarizing a ticket is routine. Judging an edge-case refund takes real reasoning. Top-tier pricing on every step wastes money; a small model on every step risks bad calls.
OT Halo’s gateway passes requests only to approved models. GMI Cloud’s Model Router then picks among them per request, weighing quality, latency, and cost, and runs the request on MaaS or dedicated Prime Inference capacity. OT Halo enforces account-level and per-agent budgets, so cost becomes part of the control loop, not a month-end surprise. In a published GMI Cloud experiment on 89 Terminal-Bench 2.1 coding tasks, a lower-cost model was enough for 70% of the tasks, depending on the agent harness, at about 26 times lower cost per trial than a premium model. Routing captures that gap. Results vary by workload. GMI Cloud also offers U.S.-based inference and zero-data-retention options, giving enterprises control over where inference runs and how data is handled.
When the agent takes action
The riskiest moment is not when the agent drafts a reply. It is when it issues the refund.
- OT Halo brokers the billing system credential, requires human approval for refunds above a set threshold, and records the action as evidence.
- GMI Cloud AgentBox runs the agent’s code and tool calls in an isolated environment, on the same cloud that serves its models, providing added protection during execution.
Built to change
Models will improve and prices will move. With policy in OT Halo and execution on GMI Cloud, adopting a new model or agent means updating policy, not rebuilding governance.
About OmniTrust Halo
OmniTrust secures the connected world, from silicon and devices to cloud systems and AI, with verifiable, enforceable trust across the device, software and AI lifecycle. Its Trust Lifecycle Management platform delivers end-to-end visibility, policy enforcement and quantum-resilient cryptography. OmniTrust Halo extends that trust to enterprise AI, helping organizations discover AI use, enforce runtime controls, protect data and intellectual property, and enable governed access to models and infrastructure. For more information, visit omnitrusthalo.com.
About GMI Cloud
GMI Cloud, an NVIDIA-backed AI compute and inference cloud, with $700M+ ARR. We are one of NVIDIA’s Exemplar Clouds, with latest GPU infra from GB300 to Vera Rubin coming next year. For teams building their own models, we offer post-training and fine-tuning on dedicated capacity with guaranteed throughput, SLAs, and data residency controls — we’ve done this for customers running domain-specific models in regulated industries. Customers include Reflection, Fireworks, Cartesia, Higgsfield, and Trend Micro. For more information, visit gmicloud.ai.